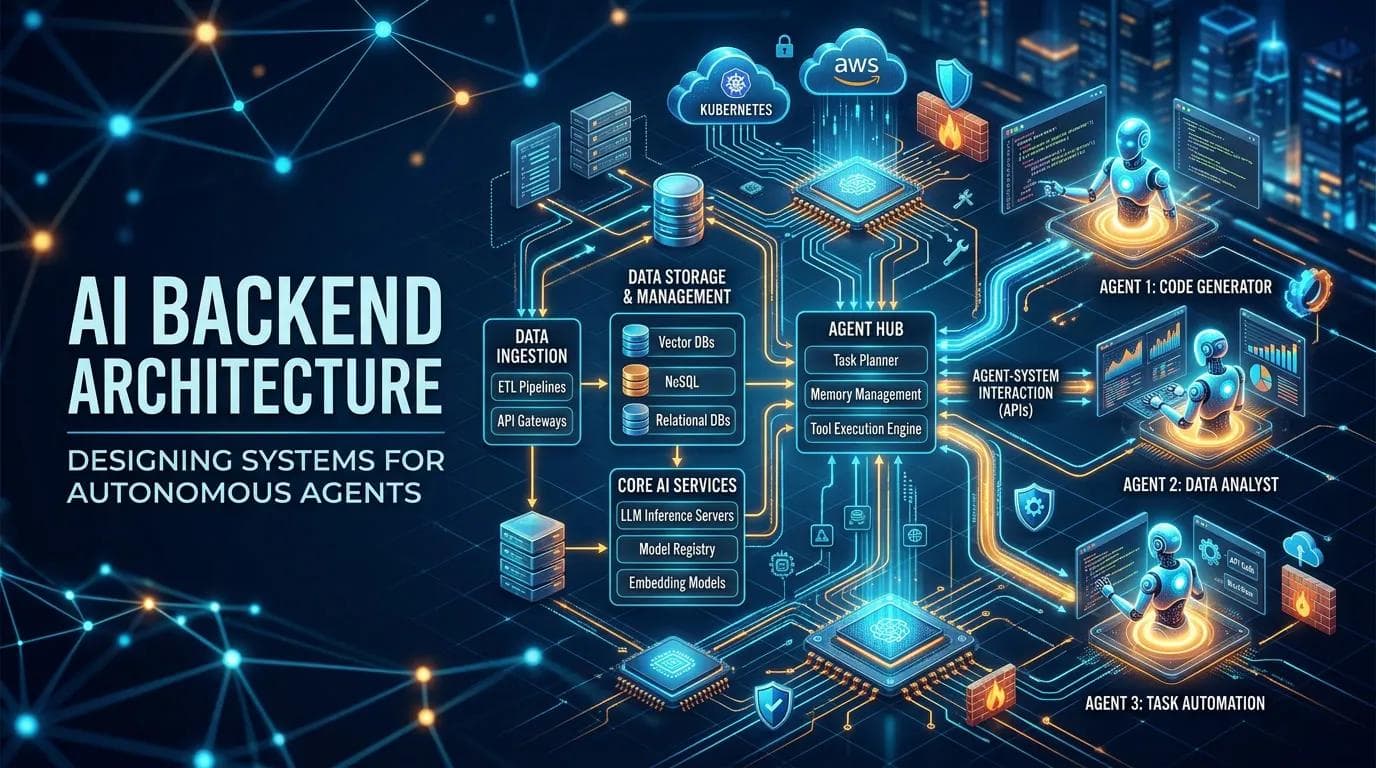
AI agent security is no longer a theoretical concern; it is an operational reality that demands immediate attention. As autonomous systems gain access to enterprise infrastructure and sensitive data, the attack surface expands rapidly. This guide breaks down recent high-profile incidents, including the Anthropic breach and specific LLM inference vulnerabilities, to provide you with concrete steps and tools to protect your AI engineering workflows. You will learn how to secure the lifecycle of an AI agent, from code scanning to runtime isolation, ensuring that your deployments remain robust against emerging threats.
The Reality of AI Agent Security Risks
AI agents introduce new security challenges that traditional software controls often miss. Unlike static applications, agents interact dynamically with external tools, APIs, and data sources, creating unique vulnerabilities through their autonomy. According to a report by eSecurityPlanet, AI agents breached Anthropic’s business systems. The report states this intrusion occurred within twelve hours, demonstrating how quickly compromised or misconfigured agents can move laterally through an organization.
This incident highlights a critical point: an agent with broad permissions is a high-value target. If an attacker can manipulate the agent's inputs or exploit a vulnerability in its tool-calling logic, they gain access to the underlying infrastructure. The speed of the breach suggests that manual monitoring is insufficient. You need automated defenses that can detect anomalous behavior in real-time.
Beyond enterprise breaches, there are deep technical vulnerabilities in how Large Language Models (LLMs) are deployed. These are not just about prompt injection; they involve the fundamental mechanics of inference engines. Understanding these layers of risk is essential for any developer deploying AI in production.
Technical Deep Dive: LLM Vulnerabilities and KV Cache Exposure
One notable vulnerability involved the GLM-5.3 Workers AI model. Cloudflare, the model's host, published a detailed post-mortem about a cross-request Key-Value (KV) cache exposure issue. This bug allowed data from one customer’s session to leak into another customer’s response.
The root cause was a misconfiguration in SGLang, an open-source inference engine. Cloudflare deployed the model with a 1,048,576-token context window, but the KV cache pool on the prefill GPUs only had room for 681,280 tokens. When a prompt exceeded the pool limit, the engine did not reject it safely. Instead, it marked the request as rejected internally, replaced it with a one-token placeholder, and generated a KV cache for that placeholder.
The critical failure occurred in the decode phase. The decode node assumed the full prompt had been processed and attended over stale cache pages that still held data from earlier requests. Consequently, responses to prompts longer than 681,280 tokens contained data from other users' sessions. Cloudflare confirmed that 155 responses were affected between August 27 and September 9, 2026.
This incident highlights a specific class of LLM vulnerabilities: state leakage in multi-tenant inference environments.
Why This Matters for Your Deployment
If you are running self-hosted LLMs or using managed services, you must verify the isolation guarantees of your inference engine. The GLM-5.3 bug was not a model flaw but an infrastructure flaw. However, it resulted in a data breach.
Key lessons from this incident include:
- Context Window vs. Pool Size: Ensure your KV cache pool is larger than your maximum context window to prevent rejection paths from being triggered under normal load.
- Rejection Handling: Verify that your inference engine safely aborts requests that exceed limits, rather than processing placeholders that might interact with stale state.
- Multi-Tenant Isolation: In disaggregated prefill/decode modes, ensure that the decode node validates the integrity of the transferred KV cache.
Cloudflare remediated this by adjusting the pool size to hold roughly 2.04 million tokens and patching the engine to retire rejected requests before any allocation or transfer happens. They also proposed upstream fixes to ensure the decode node verifies token counts.
Securing the Workflow: NVIDIA SkillSpector and Code Scanning
While infrastructure vulnerabilities are critical, the primary vector for AI agent compromise is often the code itself. Agents rely on "skills" or tools to interact with the world. If these tools contain insecure code, the agent becomes a vector for attacks.
NVIDIA has introduced SkillSpector, a security scanner designed specifically for AI agent skills and Model Context Protocol (MCP) servers. As developers increasingly rely on third-party skills to extend agent capabilities, the risk of introducing malicious or vulnerable code increases. SkillSpector scans these components for common security issues, such as injection vulnerabilities, unsafe data handling, and excessive permissions.
Integrating a scanner like SkillSpector into your CI/CD pipeline is a crucial step in AI agent security. It shifts the security check left, catching issues before the agent is deployed. For example, a skill that executes shell commands without proper sanitization could allow an attacker to run arbitrary code on the host system. A scanner can flag this pattern before it reaches production.
Implementing Scanning in Your Pipeline
You should treat AI agent skills with the same rigor as any other library. Consider these steps for integrating scanning:
- Identify Entry Points: Determine which functions in your agent code interact with external tools or user input.
- Static Analysis: Run tools like SkillSpector against your skill definitions and MCP server code.
- Dynamic Testing: Deploy the agent in a sandboxed environment with canary data to monitor for unexpected behavior.
1# Illustrative example: A basic security check for a tool definition
2# Note: This is a simplified check. Use specialized tools like NVIDIA SkillSpector for production.
3
4def validate_tool_input_schema(schema: dict) -> bool:
5    """
6    Validates that a tool schema does not contain dangerous patterns.
7    This is a placeholder for more complex analysis.
8    """
9    # Check for raw shell execution without sanitization
10    if "shell" in schema.get("function", {}).get("name", "").lower():
11        if "command" in schema.get("parameters", {}):
12            # Flag for manual review if no sanitization hint is present
13            return False
14    return True
15
16# Example usage
17tool_schema = {
18    "type": "function",
19    "function": {
20        "name": "run_shell_command",
21        "parameters": {
22            "type": "object",
23            "properties": {
24                "command": {"type": "string"}
25            }
26        }
27    }
28}
29
30if not validate_tool_input_schema(tool_schema):
31    print("Security Warning: Tool definition flagged for review.")
This snippet is illustrative. In practice, you would rely on comprehensive scanners that understand the specific semantics of AI agent frameworks.
Practical Steps to Secure Deployed Agents
Securing AI agents is a multi-layered process. You must protect the code, the infrastructure, and the runtime environment. Here are specific steps you can take immediately.
1. Enforce Least Privilege
Agents should only have the permissions necessary to perform their tasks. If an agent is designed to read logs, it should not have write access to the database. Use role-based access control (RBAC) to restrict API keys and credentials. Rotate these credentials regularly and monitor their usage.
2. Isolate the Runtime
Run AI agents in isolated environments, such as Docker containers or serverless functions. This prevents a compromised agent from accessing the host system or other services. Use network policies to restrict outbound connections to only the necessary endpoints.
3. Monitor for Anomalies
Implement logging and monitoring for all agent actions. Look for patterns that indicate a breach, such as:
- Unusual volumes of data being accessed.
- Requests to unauthorized endpoints.
- Attempts to bypass input validation.
eSecurityPlanet’s report on the Anthropic breach emphasizes the need for rapid detection. If an agent starts behaving outside its expected parameters, it should be automatically suspended.
4. Validate Inputs and Outputs
Never trust user input or output from external tools. Sanitize all data before it is passed to the LLM or used in downstream processes. Implement input validation to prevent prompt injection attacks, where a user manipulates the prompt to override the agent’s instructions.
5. Keep Inference Engines Updated
As seen with the SGLang vulnerability, bugs in inference engines can have severe consequences. Subscribe to security advisories for your inference engine and apply patches promptly. If you are using a managed service, verify their security posture and incident response procedures.
Pitfalls and When Not to Use Certain Approaches
While these measures are effective, they come with trade-offs. For example, overly strict input validation can break legitimate use cases where flexibility is required. In such cases, consider using a hybrid approach: allow flexible input but monitor the output for anomalies.
Another pitfall is over-reliance on automated scanners. While tools like NVIDIA SkillSpector are valuable, they are not infallible. They may miss novel attack vectors or context-specific vulnerabilities. Always combine automated scanning with manual code reviews, especially for critical components.
Finally, be cautious with autonomous actions. If an agent is allowed to execute code or modify infrastructure without human approval, the risk of a catastrophic failure increases. For high-stakes operations, implement a "human-in-the-loop" requirement, where the agent proposes an action and a human approves it before execution.
Key Takeaways
- AI agent security is a multi-layered challenge. You must secure the code, the infrastructure, and the runtime environment.
- LLM vulnerabilities can lead to data breaches. The GLM-5.3 KV cache exposure shows that inference engine bugs can leak sensitive data across tenants.
- Automate security scans. Use tools like NVIDIA SkillSpector to detect vulnerabilities in AI agent skills and MCP servers before deployment.
- Enforce least privilege and isolation. Restrict agent permissions and run them in isolated environments to limit the blast radius of a breach.
- Monitor for anomalies. Implement real-time monitoring to detect and respond to suspicious agent behavior quickly.
FAQ
What is the primary risk of deploying AI agents in enterprise systems? The primary risk is that agents with broad permissions can be exploited to access sensitive data or execute malicious actions. The Anthropic breach highlights how quickly this can happen.
How can I prevent KV cache exposure in my LLM deployments? Ensure your KV cache pool is larger than your context window and that your inference engine safely handles over-length requests. Keep your inference engine updated with the latest security patches.
What is NVIDIA SkillSpector? NVIDIA SkillSpector is a security scanner for AI agent skills and MCP servers. It helps detect vulnerabilities in the code that agents use to interact with external tools.
Should I always require human approval for agent actions? For high-stakes operations, yes. Human-in-the-loop requirements reduce the risk of catastrophic failures. For low-risk tasks, you may allow autonomous execution with strict monitoring.
About the Author

Suraj Kumar is a writer, entrepreneur, and the CEO and founder of this website, sharing simple and practical insights on business, creativity, and personal growth. With experience building digital projects, they enjoy helping others learn, grow, and succeed online.